NeurIPS 2026 · Accepted
Iterative Latent Refinement for Value Learning in Offline Goal-Conditioned RL
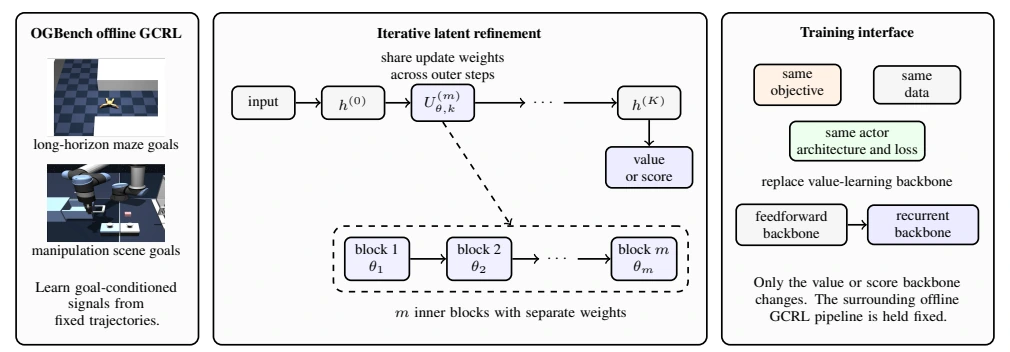
We study iterative latent refinement as an architectural replacement for the feedforward value or critic backbone used by existing offline GCRL algorithms.
The scientific question
Iterative Latent Refinement for Value Learning in Offline Goal-Conditioned RL
Offline goal-conditioned reinforcement learning enables goal reaching from static datasets, but the learned value, critic, or compatibility score must support both long horizon reachability inference and offline policy extraction.
The core idea
Iterative Latent Refinement
Instead of emitting a score after a single feedforward computation, the network repeatedly updates a latent representation using shared recurrent update weights and lightweight step specific parameters before exposing the final actor facing signal.
What we found
Evaluated OGBench Datasets
On the evaluated OGBench datasets, iterative refinement variants improve performance across several algorithms without changing their losses, data, actors configuration.
Daoxin Li and Songcheng Xu contributed equally.
Continue the question
Related reading
- Aligning Inductive Bias for Data-Efficient Generalization in State Space ModelsNeurIPS 2026 · 2026
- Representation Transfer via Invariant Input-driven Continuous Attractors for Fast Domain AdaptationCommunications Biology · 2026
Cite this work
Daoxin Li, Songcheng Xu, Guozhang Chen. Iterative Latent Refinement for Value Learning in Offline Goal-Conditioned RL. NeurIPS 2026.