arXiv · 2026 · Preprint
SFA: A Statistical Physics-Inspired Diffusion Transformer for Efficient and High-Quality Image Generation
Scale-Free Attention uses a statistical physics-inspired spatial hierarchy to accelerate high-resolution diffusion transformers while improving image generation quality.
The scientific question
Can scale-free spatial hierarchies make diffusion attention both fast and accurate?
Full self-attention scales quadratically with token count, creating a severe computational bottleneck for high-resolution image generation in diffusion transformers.
The core idea
Hierarchical Scale-Free Token Aggregation
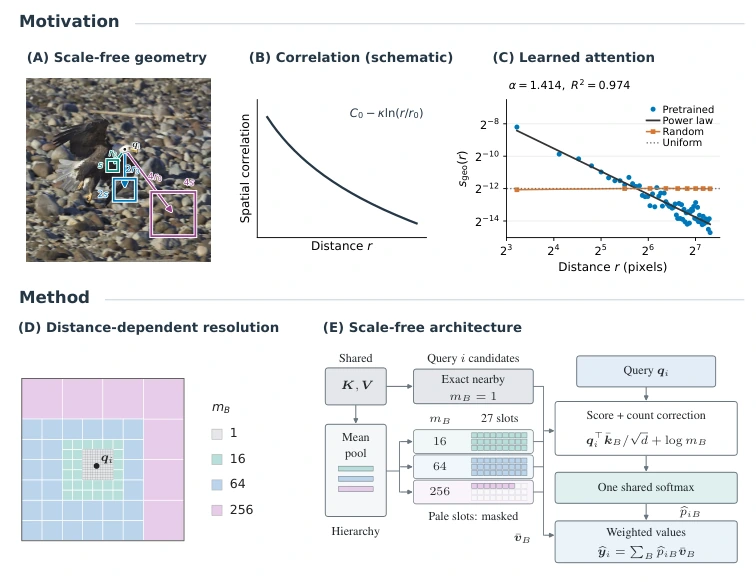
Inspired by scale-free laws in statistical physics, SFA preserves fine-grained local token interactions while summarizing distant regions at progressively coarser scales through mean pooling and token-count correction.
What we found
Log-Linear Complexity and Superior Quality
SFA reduces forward and backward attention complexity to O(N log N), delivering multi-hundred-fold kernel speedups at high token counts while outperforming full attention on ImageNet generation quality.
Continue the question
Related reading
- The Hippocampal Place Field Gradient: A Bio-inspired Framework Building Multiscale Representation for Better Sample EfficiencyICML 2026 · 2026
- Aligning Inductive Bias for Data-Efficient Generalization in State Space ModelsNeurIPS 2026 · 2026
Cite this work
Zixuan Huang, Tianhao You, Guozhang Chen. SFA: A Statistical Physics-Inspired Diffusion Transformer for Efficient and High-Quality Image Generation. arXiv, 2026. doi:10.48550/arXiv.2611.00027.